Talha Ijlal

Data · AI · LegalTech

§ 1 About

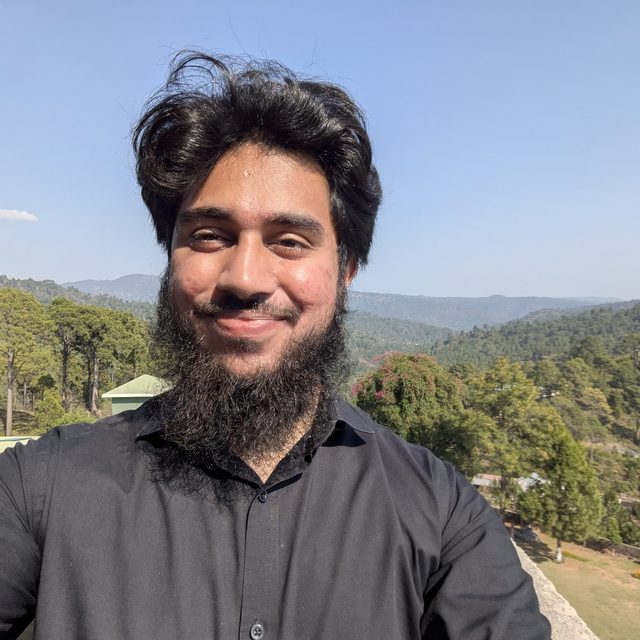
Photo of Talha Ijlal

I build the data and AI systems behind legal technology: the pipelines that turn court judgments and statutes into clean, structured data, and the retrieval layer that lets people and LLMs search it.

Since 2024 that has been DigiLawyer, where I was the founding data engineer. I've brought in about 400,000 Pakistani judgments plus case law from the UK, India and DIFC, and put semantic and full-text search over all of it in PostgreSQL. Before that I automated ad delivery monitoring at Adara with Airflow and BigQuery.

I have a CS degree from UET Lahore. I also memorised the Quran and completed the classical Dars-e-Nizami curriculum, which turned out to be good training for reading legal text closely.

§ 2 Work

2.1 DigiLawyerFounding Data Engineer

2024 – now

A legal research product built on Pakistan's laws and court judgments. I owned the data and search layer, from scraping to the queries behind user search, and led a small data team of one engineer and four interns. Users grew from about 1,000 to 16,000 while people were searching what I built.

  1. Judgment pipeline. Scrapes judgment PDFs from Pakistan's courts and other law sites, about 15 sources, then uses LLMs to extract metadata and write structured headnotes. It has processed around 400,000 judgments and takes in roughly 10,000 new ones a month.
  2. Pakistan's statutes, section by section. I designed the schema for acts, chapters and sections, built the Flask entry app, and ran a three-person team digitising about 200 sections a day. Section-level statute lookups by our AI went to roughly 80% accurate retrieval.
  3. Hybrid search on PostgreSQL. Replaced Turso + Qdrant + MeiliSearch with one PostgreSQL running pgvector and ParadeDB's pg_search, compiled into a custom Docker image. Full-text and semantic search now sit on the same rows, so a query no longer hops between three databases.
  4. Case law beyond Pakistan. Cleaned and loaded about 600,000 UK case law records, 30,000 Supreme Court of India judgments merged from two sources, and 3,000 DIFC rules.
  5. MyContract. My final-year project at UET: an AI contract drafting and compliance-check platform on Next.js, Python, Airflow and PostgreSQL. It was later merged into DigiLawyer.

2.2 AdaraData Engineer

2023 – 2024

Adara, a RateGain company, delivers advertising audience segments to 50–60 platforms like DV360, The Trade Desk and Yahoo. I worked on the Airflow and BigQuery pipelines that check those deliveries actually landed.

  1. Delivery failure detection. A team used to check by hand every day whether segments had reached each destination. We replaced that with an hourly Airflow DAG that catches failed deliveries and opens the Salesforce case itself, cutting manual monitoring by over 90%.
  2. File-based runner. Moves about 100 client files a day. New rows in BigQuery trigger a Cloud Composer DAG that fetches the files, delivers them over SFTP and writes the status back.
  3. DV360 audience sizes. A daily job tracking 40–60 segments: whether they landed, how much they grew since the day before, and when they last updated. Results went to Google Sheets.

§ 3 Other things I've built

  1. AlmaLinux server recovery. A production AlmaLinux server on UpCloud stopped booting after a root partition failure. I rebuilt GRUB from a chroot and brought it back with little downtime.
  2. SecondBite. A feed pipeline for an OpenCart store. Selenium scrapers pull from three sources, match SKUs and write through the Google Sheets API: 5,000 records on the first run, then about 100 updates a day.
  3. Tracksure Connect. A flight aggregator for small South Asian airlines that the big sites ignore.
  4. Graph text classifier. Medium articles as co-occurrence graphs, analysed with spanning trees and centrality.
  5. KIWI. Finds Fiverr keywords with lots of searches and few gigs.

§ 4 Contact

Email muhammad.talha.ijlal@gmail.com. I'm also on GitHub and LinkedIn, and my CV is here.